E-Mobility Marketplace for Beyond Move
An e-mountain bike, an e-scooter and a brake caliper belong on the same marketplace, yet have almost nothing in common in terms of what you want to know about them. For Beyond Move, Batunet therefore didn’t build the listing around fixed columns, but around an attribute model that is assigned to categories — and that drives both the input form and the filters from the same definition.
The case in one minute.
- Role
- New development of the Laravel API, Nuxt frontend and admin interface — data model, category and attribute logic, listing process, search and messaging.
- Timeframe
- Development from March to July 2021; extension from July to October 2022 with a new messaging feature and performance optimization.
- System class
- Public e-mobility marketplace. Sellers are commercial dealers and private sellers; the interface is in German.
- Product areas
- E-bikes with multi-level subdivision, e-scooters, e-skates and e-bike parts — 35 categories in a shared tree, plus a brand and model directory.
- Product data model
- Attributes aren’t fixed columns on the listing but separate field definitions with separately stored values. They are assigned to categories; the assignment carries the category path along with it.
- Shipped attribute configuration
- 17 attribute fields, assigned to the categories of the e-bike branch and to e-scooters. E-skates and e-bike parts carry none of these fields.
- Search and filters
- Category filter via the category path, brand and model filters, attribute filters with selection, text and range comparison. Location with coordinates per listing.
- Marketplace features
- Listings with status management by administration; creation, changes, deletion and status changes are logged. Plus messaging between users, seller ratings, a watchlist and per-listing contact sharing.
- Technical environment
- Laravel 8 as a REST API with token-based authentication, Nuxt 2 with server-side rendering, a Vue application for administration, MySQL.
- Scope note
- Frontend and admin interface are based on licensed UI templates that were adapted for the marketplace.
A marketplace where nothing is comparable.
A marketplace depends on making offers comparable. At Beyond Move, that is exactly the difficulty. You describe an e-mountain bike by frame type, suspension travel, motor and battery. An e-scooter by entirely different measures. A brake caliper has nothing to do with either, but belongs on the same marketplace — because anyone who buys an e-bike will eventually buy parts for it.
The obvious approach would be to write the attributes as columns on the listing. It works for one product type and breaks with the second: either you maintain a table with columns that stay empty for most listings, or you build a separate listing per product type — and with it a second marketplace next to the first.
Both approaches merely postpone the same question. The real task, therefore, wasn’t to find the right attributes, but to build the listing so that it doesn’t need to know which attributes it will eventually carry.
Attributes as data, not as columns.
In this system, an attribute isn’t a field in the code but a record. A field definition carries its type, its options, a validation rule, its order, whether it is required and whether it should appear in search and filters. The entered values are stored separately and reference the definition and the listing.
As a result, the listing splits into two layers. One is the same for every offer and is fixed on the record: title, description, images, price, condition, location. The other depends on which category the offer is in — and isn’t a programming decision but an assignment in the data.
The price of this should be stated honestly: a model like this trades database structure for flexibility. You lose the self-describing table — a look at the schema no longer tells you which attributes an e-bike has. In return, a new attribute requirement isn’t a schema change. For a marketplace whose product range changes faster than its software, that is the right trade.
- Shared listing data
- Title, description and image gallery, Price and price type, Condition, shipping availability, assembly note, Location with coordinates
- Category and taxonomy
- Category tree with a path per node, Brand and model, Copy of the path in the assignments, Category-specific page metadata
- Dynamic attributes
- Field definition with type, options and validation rule, Values stored separately from the listing, Assignment to categories, Order, required flag, search and filter flags
- Discovery
- Category filter via the path, Brand and model filters, Attribute filters with selection, text and range, Form and filters from the same definitions
The path of a listing.
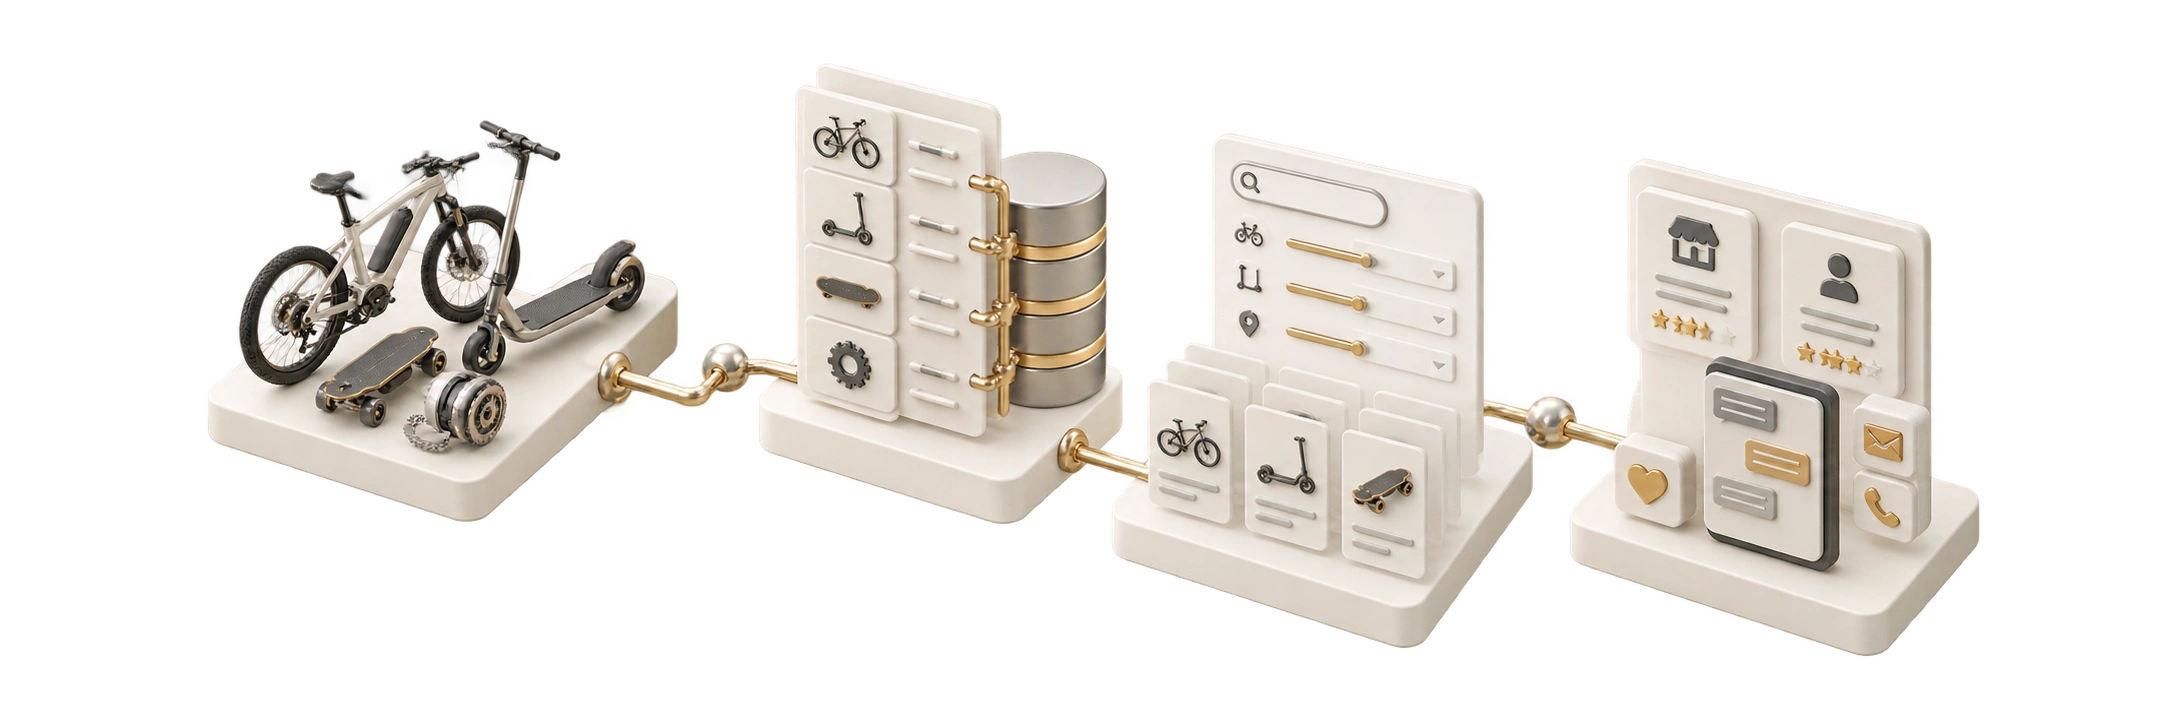
The path of a listing is where the data model shows itself. It doesn’t begin with a form but with a decision: only once the category is set is it clear what to ask for at all.
What matters here is what the frontend doesn’t do. It has no field list. For the selected category, it loads the assigned field definitions from the API and chooses the rendering per field type. The same definitions later generate the filters. Input and search therefore can’t drift apart — they come from the same source.
- 01
Choose a category
The category determines which attributes the form offers in the first place.
- 02
Load fields
The category’s field definitions come from the API; the interface has no hard-wired field list and chooses the rendering per field type.
- 03
Enter the offer
Shared listing data, brand and model, images and the attributes of the selected category. If a brand or model is missing from the directory, it can be created while listing.
- 04
Store values
The attribute values are stored separately from the listing and brought back together via the field definition.
- 05
Publish
The listing is published; administration can change its status at any time, and every status change is logged.
- 06
Become discoverable
Published listings appear in category, search and filters and can be reached via the messaging feature or the contact channels the seller has shared.
A tree that does the math.
Here, the category tree isn’t a navigation element but a calculation path. In addition to its parent reference, each category carries a path that represents its position in the tree as a string. This path is updated automatically on save, including for the nodes below it.
This has a consequence that tipped the decision: the category filter becomes a prefix comparison instead of a recursive traversal. A query for a branch finds everything beneath it in one step — listings as well as the attributes assigned to the categories of that branch.
This convenience has a downside that is part of the architecture: the path isn’t stored only on the category but also as a copy in the assignment tables for listings, attributes and brands. As long as the tree grows, that is unproblematic. If it is restructured, these copies have to be updated too. The tree is therefore extensible, but not freely reorderable — a property you need to know about before you need it.
Filter what actually exists in this category.
A filter bar that offers the same fields for every offer is useless on a mixed marketplace. That’s why the filter bar is also generated from the attribute definitions of the selected category — it shows what is actually assigned there, and nothing beyond that.
On the query side, the model requires more care than a column search. Values aren’t stored in typed columns but as separate records. Filtering therefore translates per attribute type: multi-select as a set comparison, free text as a substring search, numeric ranges as upper and lower bounds. Brand and model filters work directly on the directory, the category filter on the path.
One decision is deliberately restrictive: filtering doesn’t apply to every attribute in the request, only to those assigned to the selected category. Everything else is discarded. Without this check, an open attribute structure would become an open query interface — and flexibility in the data model must not turn into flexibility in the database query.
The marketplace stops before the purchase.
A marketplace isn’t a shop with many sellers. It doesn’t sell anything. It connects — and every mechanism it needs follows from this one property.
Sellers appear in two roles: as commercial dealers with their own profile and their own seller page that brings together their other offers, and as private sellers. A tiered role and permission model separates the editorial and administrative accounts from these. Administration controls the status of every listing; creation, changes, deletion and status changes are logged so it remains traceable afterward who changed what.
Contact between buyer and seller is part of the product: a messaging feature with history, file attachments, read receipts and email notifications, plus a watchlist and seller ratings. Whether the email address and phone number are visible is decided by the seller per listing. What deliberately doesn’t exist is a shopping cart, a checkout or a payment flow. The deal is closed between the parties involved. That isn’t a gap but the definition of the system — and it keeps an entire class of requirements out of a product that doesn’t need them.
What a model can do and what of it is used.
A data model and its configuration are two different things, and it pays to keep them apart.
The model supports category-dependent attributes, path-based queries across the category tree, type-dependent rendering and type-dependent filtering. The initial configuration that shipped used a subset of this: 17 attribute fields, individually assigned to the categories of the e-bike branch and to e-scooters, oriented in content toward bicycles. E-skates and e-bike parts carry none of these fields — they are covered by the shared listing data and the category tree.
You could read that as unfinished. We read it differently: a marketplace launches with the product range that sustains it and grows into the other areas. The difference lies in what that growth costs. In a model with fixed columns, every new product world would have been a schema change with migration and deployment. Here, it is an assignment in the data. That the capability wasn’t fully used at launch isn’t an argument against it — it’s the reason it was built.
Two stages of development.
The version history shows two phases: the new development in spring and summer 2021 and a second extension in summer and fall 2022. Smaller adjustments came in between and afterward.
- 01
March to July 2021
Laravel API, Nuxt frontend and admin interface, category and attribute model, listing process, search and filters.
- 02
Late 2021 to mid-2022
Search engine fundamentals: sitemap from the API, robots directives, canonical adjustments.
- 03
July 2022
Frontend performance optimization with code splitting and lazy loading.
- 04
August to October 2022
New messaging feature with conversations, file attachments and email notifications via a queue.
Where this case connects.
Questions about this case
How do you model completely different product types in one marketplace?
By pulling the attributes out of the listing. At Beyond Move, they aren’t fixed columns on the offer but separate definitions with separately stored values that are assigned to categories. A new attribute requirement thus becomes a data question rather than a schema change.
How does a marketplace differ from an online shop?
A shop sells; a marketplace connects. That changes almost every requirement: many sellers instead of one product range, status management of listings instead of product maintenance, contact channels between users instead of a checkout. This system deliberately has no shopping cart and no payment processing — the deal is closed between the parties involved.
Can new categories and attributes be set up without development work?
Within the intended limits, yes. Categories and attribute definitions are data, and their assignment to one another can be managed in the admin interface; the input form and filters follow the assignment without any code changes. More extensive changes — such as moving existing branches or new attribute types with their own rendering — are development work. We therefore describe configurability as what it is: broad, but not unlimited.
Why aren’t the attributes simply columns on the listing?
Because that only works for one product type. With several, it leads to a table whose columns stay empty for most records, or to separate listing types and thus to several marketplaces in one system. The trade-off we chose instead costs self-description in the database schema and care in the queries — and it is the reason the product range can grow without the software having to know about it in advance.
Why don’t you give usage figures?
Because the engineering work can be described completely without them. Product data model, category logic, listing process, search and marketplace mechanics stand on their own, and usage figures say little about the quality of a data model anyway.
Related topics.
Guides, decisions, services and case studies connected to this page.
Let’s talk about your project.
Tell us briefly about your project. Your first conversation is directly with our management.